A focused empty state avoids a blank dashboard and guides the learner toward the first useful action.

Role
Product Designer



The project
Project overview
Recognizing information is not the same as being able to explain it.
Calibrate turns personal study material into review cards designed around open recall. Learners rate their confidence, explain a concept from memory, then receive traceable feedback showing what was understood, vague or missing.
The result helps them decide what deserves attention next.
Defining the product
Product framing
User
Higher-education students learning concept-heavy subjects.
Core JTBD
Identify what I can't explain and what to review next.
MVP
Import → Recall → Diagnose → Prioritize.
Risks
AI reliability · Cognitive load · Privacy.
Understanding the problem
Research and learning principles
I synthesised principles around active recall, retrieval practice, explanation and confidence calibration to define the product hypothesis.
The goal was to explore how a study tool could move beyond recognition and repetition not to claim a validated learning outcome.
Three design hypotheses
01 — Familiarity can feel like mastery
Seeing familiar material can create confidence without proving it can be retrieved independently.
Design response: ask learners to explain before revealing the source or expected concepts.
02 — Binary feedback is not enough
A right-or-wrong result does not explain what was understood, vague or missing.
Design response: connect feedback directly to specific parts of the learner’s answer.
03 — Repetition needs prioritization
Knowing that something was difficult does not automatically tell learners what deserves attention next.
Design response: translate each answer into a learning state that shapes the next review.
Behavioral learning profiles
Rather than demographic personas, I focused on different learning behaviors: how learners revise, where false confidence can appear, and what kind of feedback could help them adjust.


Competitive audit
I reviewed common study tools to understand how they support repetition, recall and progress.
Most make it easier to review more often.
The opportunity for Calibrate was to focus instead on whether learners can explain a concept without support.
This shaped the core loop:
Confidence → Open recall → Explainable feedback → Review priority

Most tools help learners review more often, but few reveal whether they can explain a concept without support.
This gap shaped Calibrate’s core loop: confidence, open recall, explainable feedback, and review priority.
From recognition to calibrated recall
The product logic
Each review turns perceived confidence into something that can be compared with actual recall.
Confidence before feedback
Learners rate their confidence before seeing the source, expected concepts or diagnosis.
Explanation as evidence
They explain the concept in their own words, giving the system evidence of what was retrieved and what may still be missing.
Diagnosis becomes action
The result becomes a learning state that determines what deserves attention next.

Translating the logic into an experience
Key UX decisions
The challenge was to preserve the value of effortful recall while keeping the experience simple enough for repeated mobile use.
01
Reach the first useful action quickly
Calibrate only becomes useful once learners add their own material.
Instead of extending onboarding, the empty state guides new users directly toward importing their first study source.


02
Protect effortful recall
During an answer, the source material, expected concepts and learning state remain hidden.
Learners respond through voice or text, preserving the same open-recall task without giving away the answer.
03
Make AI feedback inspectable
A single score is easy to scan but difficult to trust or learn from.
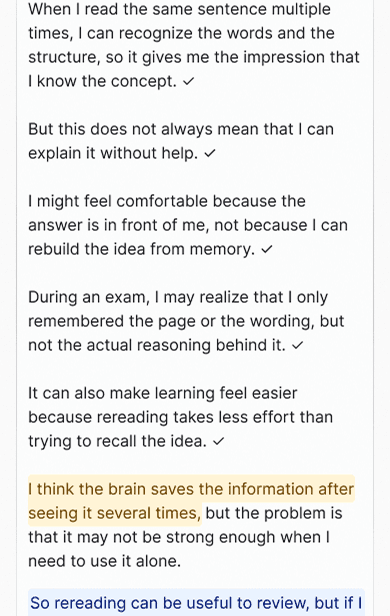
Calibrate connects feedback to highlighted parts of the learner’s own answer, showing what was strong, vague, incomplete or missing.
Global verdict
Highlighted evidence
Focused explanation
04
Turn diagnosis into the next action
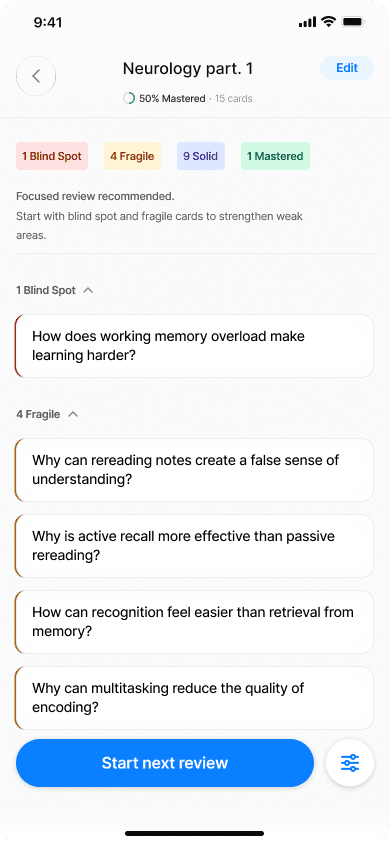
Answers are translated into four learning states:
Blind Spot · Fragile · Solid · Mastered
These states shape the recommended Smart Review while still allowing learners to choose what they want to focus on and how long they want to study.
Learning states
Card detail
Smart Review
The complete experience
End-to-end learning loop
The full experience connects imported material to a prioritized next review without breaking the same learning principle.
A focused empty state directs the learner towards the first useful action.
Different source formats can be combined within the same import.
02
Generate and inspect source-linked cards
AI creates editable review cards linked back to the imported material.

The processing state explains what the system is doing.
Generated cards can be inspected and edited before review.
03
Rate confidence and explain
Rate confidence, then explain the concept through voice or text without seeing the answer.

Confidence is captured before feedback can influence it.
Voice and text preserve the same open-recall task.
04
Inspect the diagnosis
Inspect what was understood, vague or missing through feedback connected to the learner’s response.
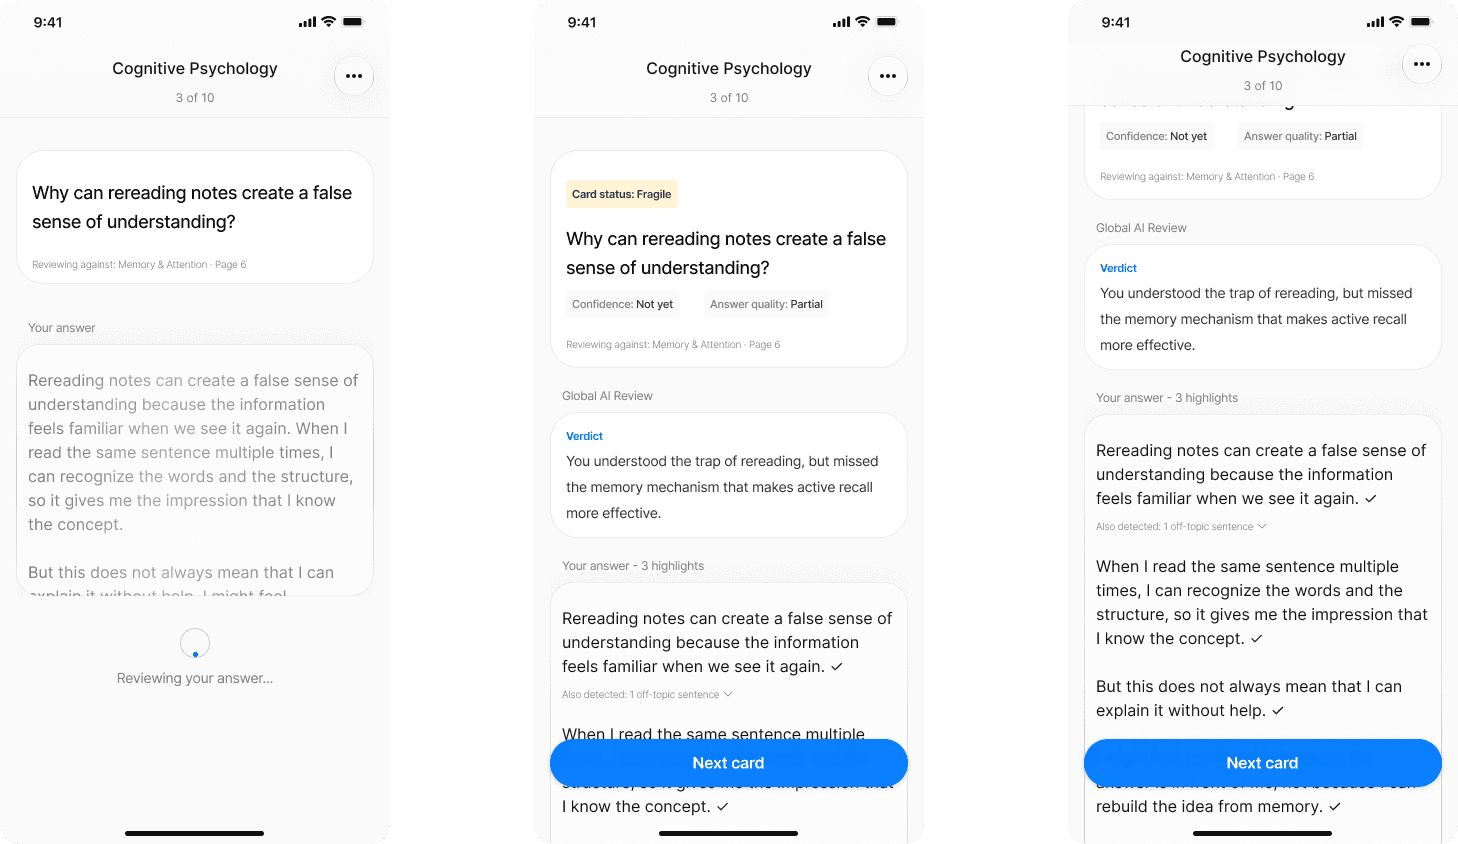
The first layer provides a quick overview.
Highlighted segments connect feedback to the learner’s own words.
Focused explanations show what could be improved.

** WCAG AA check + checkmark '✓' symbol for accessibility
05
Prioritize the next review
Use learning states to identify weak concepts, retry them or start a recommended Smart Review.

Learning states make weak areas easier to locate.
Card details combine the answer, source, and diagnosis.
Learners retain control over the next session.
Design exploration
Designing the AI review
The feedback experience was the most sensitive part of the product.
I explored three directions and compared them against scannability, explainability and actionability.
01 — Checklist feedback
The first direction separated concepts into covered, partial and missing.
It was precise and easy to audit, but fragmented the answer and made the main learning issue difficult to identify quickly.
02 — Percentage-based scoring
The second direction summarized comprehension as a percentage supported by learned, partial and missing concepts.
It was highly scannable, but reduced a nuanced explanation to a number and risked giving the score more authority than the reasoning behind it.
03 — Micro-synthesis
The third direction introduced a short written verdict identifying the main issue.
This created a stronger hierarchy, but the verdict alone still did not provide enough evidence for learners to understand how the conclusion was reached.
Final direction
The final design combines the strengths of the three explorations:
Short verdict → Highlighted evidence → Focused explanations
The verdict communicates the main learning signal quickly.
Highlighted answer segments make the diagnosis traceable to the learner’s own words, while focused explanations provide additional depth when needed.
The goal is not to make AI evaluation appear certain, but to make its reasoning easier to inspect and question.


Final reflection
Prototype outcome
Calibrate demonstrates a complete learning loop connecting:
Imported material → Confidence → Open recall → Diagnosis → Learning state → Next review
Its main contribution is not an automated score. It is a way for learners to inspect the possible gap between what they believe they know and what they can actually explain.
What the prototype demonstrates
A coherent flow from personal material to targeted review
A way to compare confidence with open-answer quality.
Feedback connected to the learner’s answer and source material.
A learning-state system that turns diagnosis into a next action.
What remains to be validated
Whether learners use the confidence input consistently.
Whether highlighted feedback feels clear and appropriately cautious.
Whether learning states help learners choose what to review next.
How reliably the AI handles alternative valid explanations.
Whether the complete flow remains manageable during longer sessions.
How privacy and data retention should be communicated.
Next experiment
The next step would be a moderated usability test with learners studying concept-heavy subjects.
I would test whether participants understand the confidence step, can interpret the diagnosis, understand why a learning state was assigned, and can choose what to review next without assistance.
How success would be measured
The core signal would be the calibration gap between confidence before answering and the quality of the resulting explanation.
Across repeated sessions, the hypothesis is that this gap should decrease as learners become better at judging what they can explain — not simply what feels familiar.
Key learnings
01
AI feedback is an interface
AI feedback should be designed as an inspectable interface, not presented as an unquestionable automated result.
02
Depth must remain usable
The challenge was to provide enough evidence to support reflection without turning every answer into a dense report.
03
The complete loop matters
The product value comes from connecting input, recall, diagnosis, prioritisation, and the next action rather than treating AI generation as an isolated feature.